Beautiful Soup is a Python library that parses HTML and XML documents into a navigable tree, so you can search and extract data with a few lines of code. Imagine you need to pull product prices from a retailer's catalogue every morning: Beautiful Soup lets you point at the right HTML elements and read them out, without writing a parser from scratch. By the end of this guide you will know how to run a complete python web scraping beautifulsoup script, understand where the library hits its limits, and know exactly when to swap in a managed API instead.
What is Beautiful Soup in Python?
Beautiful Soup (imported as bs4) is a parsing library, not a scraping framework. It takes an HTML or XML string, builds a tree of Python objects that mirrors the document structure, and gives you methods to search and navigate that tree. It does not fetch pages, execute JavaScript, or manage proxies. Those jobs belong to other tools, and understanding that boundary is the key to using Beautiful Soup well.
The current release is Beautiful Soup 4 (package name beautifulsoup4 on PyPI, import name bs4). Python 2 support was dropped after version 4.9.3, so all new work targets Python 3. Beautiful Soup 3 is no longer maintained, so if you see older tutorials importing BeautifulSoup from BeautifulSoup (without the 4), they are using the legacy version.
One design choice that makes Beautiful Soup particularly useful for real-world scraping: it is a forgiving parser. It handles poorly structured HTML with unclosed tags and mismatched nesting, the kind of tag soup that real websites ship with, and still builds a usable tree. That tolerance is why it became the default first tool for Python scrapers.
How Beautiful Soup fits into a Python scraping pipeline
Beautiful Soup is a parser, not a fetcher. It never makes a network request. You always need a separate tool to get the HTML first, then hand it to Beautiful Soup for parsing. The standard pairing is:
requests: sends the HTTP GET request and returns the raw HTML response.BeautifulSoup: takes that HTML string, parses it into a tree, and gives you methods to find elements.- A headless browser or scraping API (optional): required when the page loads content via JavaScript after the initial response, because
requestsonly sees the initial HTML and Beautiful Soup only sees whatrequestsgives it.
That three-layer model covers almost every scraping task. The sections below walk through each layer in order.
Try it yourself
Run this on your own pages
Get a free API key and make your first call in minutes. 5,000 free credits for 7 days, no card.
What is Web Scraping?
Web scraping is the automated process of extracting data from websites. It is essentially like copying information from a webpage manually, but done programmatically, allowing large amounts of data to be collected quickly and efficiently.
Web scraping has two core parts:
Sending HTTP GET Requests:
Using libraries like requests in Python, you send a GET request to a website's server. The server responds with the HTML content of the webpage.
HTML Parsing:
After retrieving the HTML content, you use a library like Beautiful Soup to parse the document. Parsing converts the HTML into a structured format that can be manipulated and used to extract specific data points.
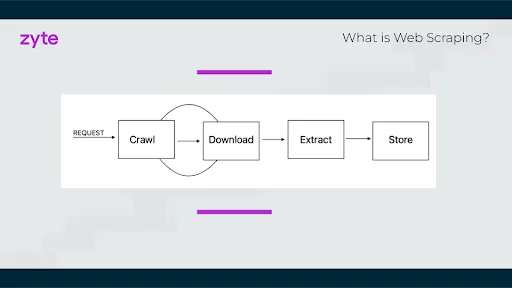
Here is the exact 7-step flow you will use to go from a URL to clean JSON on disk.
Steps Involved in Web Scraping
Step 1: Identify Your Target
- Determine the website from which you want to scrape data.
- Check if it provides APIs (Application Programming Interface) to extract the information you need.
- Ensure the website allows web scraping by checking its terms of service and robots.txt file.
Step 2: Inspect the Website Structure
- Use a browser's developer tools (F12 or Ctrl + Shift + I) to view the website's HTML code.
- Understand how the data you want is organized on the webpage. If it is loaded dynamically through JavaScript, you would need to integrate headless browser libraries like Playwright, Puppeteer, or Selenium.
Step 3: Crawl the website.
- Navigate through multiple web pages to find the data you need.
- Use a web crawler or a spider to traverse the website's pages.
Step 4: Download
- Download the HTML content of the web pages using a library like Requests in Python.
Step 5: Extract
- Extract the specific data points from the HTML content using parsing techniques.
- Use a library like Beautiful Soup in Python to parse the HTML code and pinpoint the data elements.
Step 6: Store
Save the extracted data into a structured format like:
- CSV (comma-separated values)
- JSON (JavaScript Object Notation)
- Database
These formats allow for easy import into spreadsheets or databases for further analysis.
Run the final script and you should find quotes.json on disk with every quote and author from the page. The next section covers the Beautiful Soup methods that make the extraction step more precise.
Why use Python for Web Scraping?
With requests and bs4, a 20-line script can fetch and parse a static page in under a second. That combination handles the two core jobs cleanly: requests sends the HTTP request and gives you the raw HTML; Beautiful Soup turns that HTML into a searchable tree. Add json from the standard library and you have a complete extract-and-store pipeline with no extra dependencies. When you need to go further, the ecosystem scales with you: Scrapy for crawling thousands of pages, Playwright or Selenium for JavaScript-heavy sites, and a managed scraping API when bot protection blocks plain requests.
Installing Beautiful Soup
Install both libraries with pip, ideally inside a virtual environment:
pip install beautifulsoup4 requests
The beautifulsoup4 package ships with Python's built-in html.parser, which requires no extra install and works well for most pages. If you need faster parsing or better handling of broken HTML, install lxml separately (pip install lxml) and pass 'lxml' as the parser name instead of 'html.parser'. For most tutorial and production use, html.parser is the right starting point.
Web scraping with Python using Beautiful Soup
Let's follow the above steps in web scraping using the BeautifulSoup and Requests library.
Step 1: Identify Your Target Website/Websites
We will use https://scrape.li/quotes/ as a target website for this tutorial. It serves static HTML quotes with the same structure as the classic scraping sandbox, so the code runs reliably.
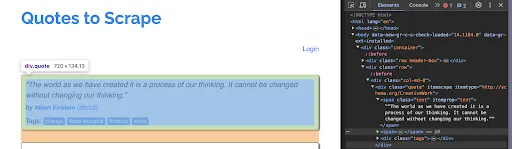
Step 2: Inspect the Web Page
- Open the web page you want to scrape in a browser.
- Inspect the HTML structure of the page using the browser's developer tools (F12 or Ctrl + Shift + I).
- Identify the HTML elements that contain the data you want to extract. In this tutorial, we will extract the quotes and their author names.
Step 3: Send an HTTP Request to the Web Page
Use the Requests library to send an HTTP request to the web page:
import requests

url = 'https://scrape.li/quotes/'
response = requests.get(url)
Step 4: Parse the HTML Content
Use Beautiful Soup to parse the HTML content of the web page. You create a BeautifulSoup object by passing the HTML string and the parser name:
from bs4 import BeautifulSoup

soup = BeautifulSoup(response.content, 'html.parser')
From here, you can navigate the tree with dot notation (soup.title, soup.body) or search it with methods. For example, soup.title.string returns the page title as a plain string, and soup.a["href"] returns the href attribute of the first anchor tag, using dictionary-style attribute access.
Step 5: Find the Desired HTML Elements
Use Beautiful Soup's methods (e.g., find, find_all) to locate the HTML elements that contain the data you want to extract:
quotes = soup.find_all('div', {'class': 'quote'})
Step 6: Extract the Data
Extract the data from the HTML elements using Beautiful Soup's methods. Use .text (or .get_text()) to pull the visible text from a tag, and call .strip() on it to remove leading and trailing whitespace:
quotes_data = []

for quote in quotes:
    author = quote.find('small', {'class': 'author'}).text.strip()
    quote_text = quote.find('span', {'class': 'text'}).text.strip()
    quotes_data.append({
        'quote': quote_text,
        'author': author
    })
Step 7: Store the Data
Store the extracted data in a format of your choice (e.g., CSV, JSON, database):
import json

with open('quotes.json', 'w') as f:
    json.dump(quotes_data, f, indent=4)

print("Data stored in quotes.json")
The final code looks like this:
import json
import requests
from bs4 import BeautifulSoup

url = 'https://scrape.li/quotes/'
response = requests.get(url)
soup = BeautifulSoup(response.content, 'html.parser')
quotes = soup.find_all('div', {'class': 'quote'})

quotes_data = []
for quote in quotes:
    author = quote.find('small', {'class': 'author'}).text.strip()
    quote_text = quote.find('span', {'class': 'text'}).text.strip()
    quotes_data.append({
        'quote': quote_text,
        'author': author
    })

with open('quotes.json', 'w') as f:
    json.dump(quotes_data, f, indent=4)

print("Data stored in quotes.json")
The output looks like this:
[
    {
        "quote": "\u201cThe world as we have created it is a process of our thinking.\u201d",
        "author": "Albert Einstein"
    },
    {
        "quote": "\u201cIt is our choices, Harry, that show what we truly are, far more than our abilities.\u201d",
        "author": "J.K. Rowling"
    },
    {
        "quote": "\u201cThere are only two ways to live your life. One is as though nothing is a miracle.\u201d",
        "author": "Albert Einstein"
    }
]
If your file matches this structure, the scraper is working correctly. Each object holds exactly two keys, quote and author, which is the shape the rest of the pipeline expects.
Key Beautiful Soup methods every scraper uses
Once you have a soup object, three methods cover the vast majority of real scraping work.
find(tag, attrs): Returns the first matching element, orNoneif nothing matches. Use it when you expect exactly one result: a page title, a price, a login form.find_all(tag, attrs): Returns a list of every matching element. Use it for repeating structures: product cards, table rows, search results. Iterate the list to extract each item.select(css_selector): Accepts a CSS selector string and returns a list, the same wayfind_alldoes. Useful when the element you want is easier to describe as.product-card > h2than as a tag-plus-attribute pair.
You can also pass a regular expression to find_all() to match tag names or attribute values by pattern, which is useful when class names are generated dynamically and share only a common prefix.
For navigating the tree beyond search, Beautiful Soup exposes relationships between tags: .parent moves up one level, .contents returns a tag's direct children as a list, and .next_sibling and .previous_sibling move across elements at the same level. These are most useful when the data you need sits adjacent to a label rather than inside a predictable class.
A quick rule of thumb: use find for unique elements, find_all or select for collections. If find returns None when you expected a result, the element is either named differently than you think, or it is loaded by JavaScript after the initial HTML response, which Beautiful Soup never sees.
Drawbacks and limitations of using BeautifulSoup
Beautiful Soup shines for static pages, but it stops at the first JavaScript request or bot check. The moment a site loads its prices via a React component, or Cloudflare intercepts your request, Beautiful Soup has nothing to work with because it only sees the HTML string you hand it. Here are the specific limits that matter when you scale.
BeautifulSoup is not suitable for large-scale web scraping because:
-
It only parses the initial HTML response and does not execute JavaScript code. This means it cannot extract content that is generated dynamically by JavaScript.
-
It has no built-in support for handling anti-scraping measures such as CAPTCHAs, rate limiting, or IP blocking. Adding a
User-Agentheader to yourrequestscall buys a little time on some sites, but it does not solve bot detection at any meaningful scale. -
It is not thread-safe, which means it is not suitable for use in multi-threaded or multi-process environments without care.
-
It can be slow, particularly when handling large documents or complex HTML structures. This is due to the need to parse the entire document and construct a tree-like data structure in memory. As a result, for large-scale web scraping involving numerous pages, BeautifulSoup can become both slow and memory-intensive.
Beautiful Soup vs a managed scraping API: where each one fits
Beautiful Soup is a parser, not a scraping stack. It reads HTML you hand it and helps you find things inside it. Everything else, fetching the page, rotating proxies, solving CAPTCHAs, executing JavaScript, managing concurrency, is your problem. That distinction matters a lot once you move past a personal project.
Here is how the two approaches compare across the dimensions that cause the most pain at scale:
| Dimension | Beautiful Soup (DIY) | Managed scraping API |
|---|---|---|
| JavaScript rendering | Not supported. You must add Playwright or Selenium separately, which adds complexity and resource cost. | Built in. Pass js=true and the API runs a real browser for you. |
| Anti-bot and CAPTCHA | None. You handle headers, fingerprinting, and CAPTCHA solving yourself. | Handled automatically. Residential proxy rotation, browser fingerprinting, and optional CAPTCHA solving are included. |
| Proxy management | You source, rotate, and pay for proxies separately. | Included in the request. Rotating residential or datacenter proxies are selected per request. |
| Concurrency | Limited by your machine and network. Scaling requires infrastructure work. | Handled by the API. Plans include defined concurrency limits so you do not have to manage a thread pool. |
| Maintenance | You own every breakage: site layout changes, new bot detection, IP bans. | The provider absorbs most breakage. Your parsing logic may still need updates, but the fetch layer is maintained for you. |
| Cost model | Low marginal cost per request, but real engineering time to build and maintain the stack. | Pay per successful request. Blocks, timeouts and server errors are not billed. |
The right choice depends on what you are scraping. Beautiful Soup is genuinely excellent for:
- Static, permissive sites: public data sources, your own test pages, sites with no bot protection.
- One-off or low-volume tasks: a script you run once a week against a site that never changes.
- Learning and prototyping: understanding HTML structure before committing to a production pipeline.
A managed API earns its place when:
- The target renders content with JavaScript: single-page apps, infinite scroll, lazy-loaded prices.
- The site actively blocks scrapers: Cloudflare, Akamai, DataDome, or aggressive rate limiting.
- You need reliable uptime at scale: hundreds of concurrent requests without building your own proxy infrastructure.
- Engineering time is the bottleneck: maintaining a DIY stack costs more than the API fee.
Replacing the fetch layer: Beautiful Soup plus a scraping API
The two tools are not mutually exclusive. A common production pattern is to use a managed API for the fetch step (getting clean HTML reliably) and Beautiful Soup for the parse step (extracting the fields you need). This keeps your parsing logic familiar while offloading the hard parts.
Here is what that looks like with Ujeebu's Scrape API. The js=true parameter tells the API to render JavaScript before returning HTML, and proxy_type=rotating rotates IPs automatically:
curl -X GET 'https://api.ujeebu.com/scrape?url=https://scrape.li/quotes/&js=true&proxy_type=rotating' \
  -H "ApiKey: YOUR_API_KEY"
import requests
from bs4 import BeautifulSoup
import json

# Fetch the rendered HTML via Ujeebu
response = requests.get(
    'https://api.ujeebu.com/scrape',
    params={
        'url': 'https://scrape.li/quotes/',
        'js': True,
        'proxy_type': 'rotating',
    },
    headers={'ApiKey': 'YOUR_API_KEY'}
)

html = response.json()['html']

# Parse with Beautiful Soup as normal
soup = BeautifulSoup(html, 'html.parser')
quotes_data = []

for quote in soup.find_all('div', {'class': 'quote'}):
    quotes_data.append({
        'author': quote.find('small', {'class': 'author'}).text.strip(),
        'quote': quote.find('span', {'class': 'text'}).text.strip(),
    })

with open('quotes.json', 'w') as f:
    json.dump(quotes_data, f, indent=4)

print(f"Extracted {len(quotes_data)} quotes")
Your Beautiful Soup parsing code stays exactly as it was. The only change is where the HTML comes from: instead of a plain requests.get, you call the Scrape API, which handles JavaScript rendering, proxy rotation, and anti-bot evasion before handing you the HTML. For sites that block scrapers or load content dynamically, this single swap is often all you need. See the Scrape API docs for the full list of parameters, including wait_for (wait for a CSS selector before returning), auto_captcha_solve, and proxy_country.
If you want to skip HTML parsing entirely and get structured data directly, the Article Extractor pulls article content as clean JSON and the Markdown API converts any page to clean Markdown, which is useful for feeding scraped content into an LLM pipeline. You can try both on the playground without writing any code.
By following these steps, you can set up a basic web scraping script to gather data from a target website. Libraries like Beautiful Soup make web scraping manageable and efficient. However, it is important to be aware of the limitations of using Beautiful Soup, especially when scaling up your projects. Challenges such as handling JavaScript-generated content, anti-scraping measures, and performance issues with large-scale scraping need to be addressed.
For those looking to scale their web scraping efforts without getting bogged down by the complexities of handling proxies, JavaScript execution, and other technical hurdles, consider using Ujeebu. Ujeebu offers a robust API that simplifies the web scraping process, managing all the behind-the-scenes difficulties for you. The free trial includes 5,000 credits with no credit card required, so you can test it against your actual target before committing. Start for free.
FAQ
What is Beautiful Soup in Python?
Beautiful Soup is a Python library for parsing HTML and XML documents. It takes raw HTML, builds a parse tree, and gives you methods like find() and find_all() to locate elements by tag, class, attribute, or CSS selector. It does not fetch pages or execute JavaScript: you pair it with requests for fetching and a headless browser or scraping API when JavaScript rendering is needed.
How do I install and import Beautiful Soup?
Install with pip: pip install beautifulsoup4. Then import it in your script with from bs4 import BeautifulSoup. Note that the package name on PyPI is beautifulsoup4, but the import name is bs4. You will also need pip install requests for the HTTP fetch step.
Can Beautiful Soup scrape JavaScript-rendered pages?
Not on its own. Beautiful Soup only parses the HTML string you give it. If a page loads its content via JavaScript after the initial response, the HTML you fetch with requests will be empty or incomplete. You need either a headless browser (Playwright, Selenium) or a scraping API with js=true to get the rendered HTML first, then pass that to Beautiful Soup.
What is the difference between find and find_all in Beautiful Soup?
find() returns the first matching element (or None if nothing matches). find_all() returns a list of all matching elements, which you then iterate over. Use find when you expect exactly one result (a page title, a price field), and find_all when you need every instance of a repeating element (all product cards, all table rows).
How do I use CSS selectors with Beautiful Soup?
Use the select() method, which accepts a standard CSS selector string and returns a list of all matching elements. For example, soup.select('.quote > span.text') returns every quote text span that is a direct child of a .quote div. select() is often more concise than find_all() when the selector involves nesting or multiple classes, and it behaves the same way: iterate the result list to extract each item.
When should I use a scraping API instead of Beautiful Soup?
Use a scraping API when the site renders content with JavaScript, actively blocks scrapers with tools like Cloudflare or CAPTCHA challenges, or when you need to run many concurrent requests without building your own proxy infrastructure. Beautiful Soup remains the right choice for parsing the HTML once you have it, and the two tools work well together: the API handles the fetch, Beautiful Soup handles the parse. See the web scraping tools overview for a broader comparison of the ecosystem.
How do I scrape web data to JSON with Beautiful Soup?
Parse the page with Beautiful Soup, collect your extracted fields into a list of dictionaries, then write it out with Python's built-in json module: json.dump(data, f, indent=4). The complete example in the tutorial above does exactly this, saving each quote and author as a JSON object. If the target site blocks plain requests calls, fetch the HTML through a scraping API first and pass the returned HTML string to BeautifulSoup() as shown in the API integration example.
How do I use BeautifulSoup with proxies?
Beautiful Soup itself has no proxy support because it never makes network requests. Proxy handling belongs to the fetch layer. With requests, you can pass a proxies dict to requests.get(). At scale, managing a rotating proxy pool yourself is complex: sourcing IPs, handling bans, and rotating sessions. A managed scraping API handles all of this per request, so you do not need to configure proxies in your Beautiful Soup code at all. See mastering web scraping proxies for a deeper look at the options.
How long does it take to learn web scraping with Python?
The time it takes to learn web scraping with Python depends on several factors, such as your prior experience with Python and programming in general, the complexity of the web scraping tasks you want to accomplish, and the amount of time you dedicate to learning and practicing.
However, with consistent effort, you can learn the basics of web scraping with Python in a few weeks to a few months. Here is a rough estimate:
- Basic understanding of web scraping concepts and tools: 1 to 2 weeks
- Ability to scrape simple websites: 2 to 4 weeks
- Ability to scrape complex websites with JavaScript rendering: 2 to 6 months
- Mastery of advanced web scraping techniques and tools: 6 to 12 months
What are the benefits of using Beautiful Soup to scrape web data?
Beautiful Soup is a popular Python library for web scraping, and its benefits include:
- Easy to learn and use, even for those without extensive programming experience
- Supports various parsing engines, including lxml and html5lib
- Allows for easy navigation and searching of the parsed document tree
- Handles broken or malformed HTML documents gracefully
- Extensive community support and documentation
What is the best way to web scrape in Python?
The best way to web scrape in Python follows a layered approach, where each layer handles one job:
- HTTP client (
requestsor Scrapy): Fetches the raw HTML. Start here; swap in a managed scraping API if the site blocks plain requests, as covered in the Scrape API section above. - HTML parser (Beautiful Soup or lxml): Extracts the fields you need from the HTML string. Beautiful Soup is the readable choice; lxml is faster for very large documents.
- JavaScript rendering (Playwright, Selenium, or
js=trueon a scraping API): Required when the page loads content after the initial response. Add this layer only when you confirm the data is missing from the plain HTML. - Anti-bot handling (proxy rotation, CAPTCHA solving): Needed for any site with bot protection. A managed API absorbs this layer entirely; a DIY stack requires sourcing and rotating proxies yourself.
- Storage (JSON, CSV, or a database): Write extracted data into a structured format immediately. JSON works for exploration; a database is better for anything you query repeatedly.
- Error handling and logging: Wrap each request in a try/except, log HTTP status codes, and retry on transient failures. Silent failures are the most expensive kind.
- Respect
robots.txtand terms of service: Check both before you start. The web scraping legality guide covers what the rules actually mean in practice.
What is the purpose of BeautifulSoup in Python?
Beautiful Soup is a Python library used for web scraping, specifically for parsing and navigating HTML and XML documents. Its primary purpose is to:
- Parse HTML and XML documents into a tree-like data structure
- Allow for easy navigation and searching of the parsed document tree
- Extract specific data from the document, such as text, links, or images
What is the Python library for scraping data?
There are several Python libraries for web scraping, including:
- Beautiful Soup (BS4)
- Scrapy
- Selenium or Playwright (for JavaScript-heavy pages)
- Requests
- LXML
- PyQuery
Each library has its strengths and weaknesses, and the choice of the library depends on the specific web scraping task at hand.
Can Python scrape a website?
Yes, Python can be used to scrape websites. Python's versatility, combined with its extensive libraries and tools, make it an ideal language for web scraping. With Python, you can:
- Send HTTP requests to websites using libraries like requests or urllib
- Parse HTML and XML documents using libraries like Beautiful Soup or lxml
- Extract dynamic data from websites using libraries like Selenium or Playwright
- Store scraped data in structured formats like CSV, JSON, or databases
However, it is essential to respect website terms of service and robots.txt files and to avoid scraping websites that explicitly prohibit web scraping.
For a deeper look at Python scraping techniques beyond Beautiful Soup, see Mastering HTML Text Extraction in Python and How to Scrape Stock Market Data using Python.
Try it yourself
Run this on your own pages
Get a free API key and make your first call in minutes. 5,000 free credits for 7 days, no card.